Quantitative Research: Methods, Statistics, and Frameworks for Product and UX Teams
Learn the 5 quantitative research designs, 10-step process, statistical decision rules, and 12 tools, with UX-specific guidance for product teams.
Updated 13 min read
Quantitative research is the systematic collection and analysis of numerical data to measure variables, compare groups, test relationships, and generalize findings to wider populations. Unlike qualitative research, which explores meaning and context through words and observations, quantitative research centers on measurement: every variable has a number, and every conclusion carries an uncertainty estimate.
For UX and product teams, the distinction shows up in daily work. Task completion rates, System Usability Scale scores, A/B test outcomes, and funnel conversion data are all quantitative research. So are the surveys that inform product roadmaps and the log-data analyses that catch drop-off points before they cost revenue.
The skill now shows up in hiring decisions: in a May 2026 r/UXResearch thread, a qualitative-leaning researcher said a senior UXR rejection cited "a lack of quantitative skills."
This guide covers five study designs, a 10-step process, and a statistical decision framework with reliability benchmarks. It also includes 12 tools with community-validated context and eight common mistakes that produce convincing numbers that mean nothing.
Key Takeaways
Quantitative research tests measurable hypotheses using structured instruments, statistical analysis, and larger samples designed for population-level inference.
Five study designs serve different questions: descriptive, correlational, causal-comparative, experimental, and longitudinal/cross-sectional.
Sample size is set before data collection via power analysis; sample sizes computed after the fact are a common source of underpowered studies.
Statistical test selection follows a decision rule: question type × measurement scale × sample distribution.
For UX teams, quantitative methods cover task success rates, SUS scores, A/B tests, and log-data analysis, a skill set that goes well beyond survey design.
What Is Quantitative Research?
Quantitative research centers on measurement, variables, and statistical reasoning to answer questions about how many, how much, or how strongly. You start with a theory or hypothesis (deductive approach), collect structured data, apply statistical methods to evaluate the result, and interpret findings with explicit uncertainty estimates (confidence intervals, p-values, effect sizes).
Its core characteristics are numerical data, structured instruments, deductive reasoning, statistical analysis, larger sample sizes, an objectivity aim, and generalizability.
What quantitative research can show: frequencies, proportions, averages, group differences, variable associations, temporal trends, and (under the right design) causal relationships. What it cannot show: why a finding exists, what participants meant by an answer, or context that was never operationalized into a variable. That boundary is the design constraint that makes quantitative findings replicable and generalizable.
Why Quantitative Research Matters for Product Teams
Stakeholders respond to numbers: "eight of twelve participants preferred the new design" carries less force in a sprint review than "task completion improved from 62% to 79% with statistical significance at p = 0.02."
UX statistics feed product roadmaps, investment decisions, and feature prioritization, so researchers who can design and analyze quantitative studies have an edge.
u/Insightseekertoo in r/UXResearch (May 2026) describes the stakes: "I recently lost a contract because I told them I was a mixed methods researcher, and they really just wanted a Quant expert. I did not know how to write the JavaScript to make the app they were using behave differently."
Learning quantitative methods incrementally (surveys first, then usability testing benchmarks, then log-data analysis, then regression) is a practical way to close that gap.
How Quantitative Research Works: A 10-Step Process
Here is the process that academic researchers, product teams, and market researchers all follow, collapsed to its core decisions.
Step 1: Define the Research Problem and Objectives
Operationalize abstract concepts into measurable variables before touching data. "User satisfaction" only becomes a variable once operationalized, for example as "System Usability Scale score on a 10-item survey," a measurable output with published reliability benchmarks. This step determines everything downstream: which design fits the question, which instruments measure the variables, and what sample size is sufficient.
Step 2: Review the Literature and Establish a Theoretical Framework
Understand what is already known. Literature review prevents re-answering settled questions, surfaces validated instruments (instead of building from scratch), and locates the theoretical framework that connects your variables. A core practice is identifying gaps explicitly: your study contributes something reviewers of existing work could not find.
Step 3: Formulate Research Questions and Hypotheses
Specify direction, scales, and minimum meaningful effect sizes before collecting data. A directional hypothesis ("Group A will score higher than Group B") commits you to a one-tailed test and a specific effect size threshold: both required inputs for the power analysis in Step 4. Starting data collection without hypotheses is one of the most common mistakes in applied research (see "Common Mistakes" below).
Step 4: Choose Study Design and Sampling Strategy
Match design to research question using the five-design taxonomy in the next section. Then compute your sample size via power analysis: specify the significance threshold (α = 0.05), desired power (0.80), and minimum meaningful effect size (Cohen's d, r, or f depending on design).
For a descriptive survey estimating prevalence (p ≈ 0.5, margin ±5%, 95% confidence): n ≈ 385, from the standard formula 1.96² × 0.25 ÷ 0.05². For detecting a medium correlation (r = 0.30), Jacob Cohen's power tables give n ≈ 85. For a two-sample t-test at medium effect (d = 0.5), they give n ≈ 64 per group.
Step 5: Develop or Select Instruments
Existing validated scales are preferable to custom ones for two reasons: they have published reliability benchmarks, and they let you compare findings across studies. Pilot-test any new or adapted instrument with a small group before full deployment. Check internal consistency (by common rule of thumb, Cronbach's α ≥ 0.70 is acceptable and ≥ 0.80 good) and test-retest reliability (ICC ≥ 0.75 is good) before treating the scale as measurement.
Step 6: Plan Data Collection and Ethics
Define exact procedures, data management protocols, and consent forms. In academic and other institutional research with human participants, institutional review board (IRB) or ethics committee review typically comes before data collection. Industry UX studies rarely go through an IRB, but informed consent and data protection still apply.
Step 7: Clean Data and Run Exploratory Analysis
Before running inferential tests, understand the data you have. Visualize distributions, identify outliers, assess missingness patterns (random or systematic?), and check statistical assumptions (normality, homogeneity of variance) for the tests you plan to run.
"All too often at Grad Coach we see students rushing past the descriptives in their eagerness to get to the more exciting inferential methods and then landing up with some very flawed results. Don't be a sucker: give your descriptive statistics all the love and attention they deserve." Emma, Grad Coach TV
Step 8: Run Statistical Analysis
Descriptive statistics first (means, medians, standard deviations, percentages): they tell you what you observed. Then inferential statistics, following the decision table in the "Statistical Analysis" section below. Report effect sizes and confidence intervals alongside p-values; a p-value alone does not tell you whether a finding matters.
Step 9: Interpret Results
Name limitations explicitly: a cross-sectional survey cannot prove causation, and a correlational finding cannot establish which variable came first. Every sample (even a well-powered probability sample) has uncertainty captured by confidence intervals.
Report the analysis honestly: statistical significance at small effect sizes (p < 0.05, d < 0.2) does not imply a meaningful difference.
Step 10: Report and Disseminate
Transparent methods and reproducible analysis are the two requirements that make a quantitative study useful to anyone beyond the original team. Include a data and code availability statement. Pre-registration (recording your hypotheses and analysis plan before seeing data) is a strong safeguard against post-hoc rationalization.
Types of Quantitative Research Design
Descriptive Research
Descriptive studies record characteristics, frequencies, averages, and distributions without explaining why. Use this design when you need a baseline (a snapshot of how many, how often, or how much) before hypothesis testing is possible.
Example: surveying smartphone-addiction agreement rates among adolescents. Prevalence is the target, so the n ≈ 385 benchmark from Step 4 applies.
Correlational Research
Correlational studies examine whether variables are related without manipulating conditions. The design describes association and enables prediction, but not causation. As Grad Coach states: "Correlation does not equal causation, so be sure to exercise caution when you interpret correlational findings and don't make the mistake of drawing causal inferences based solely on correlational research." (YouTube)
Example: whether study hours correlate with GPA.
Causal-Comparative / Quasi-Experimental Research
Causal-comparative designs compare pre-existing groups without random assignment. They are useful when randomization is impractical or unethical: comparing test scores of students who self-selected tutoring vs. those who did not, or evaluating a curriculum implemented in one district but not another. Pre-existing group differences must be controlled statistically; the design cannot definitively establish causation.
One practical advantage: quasi-experiments can operate at larger scale than true experiments, which increases statistical power for detecting smaller effects.
Experimental Research (True Experiment)
True experiments manipulate one variable (the independent variable), hold others constant, and observe a second variable (the dependent variable). Random assignment is the defining feature: it distributes confounds across groups and makes causal inference valid. PMC identifies randomized controlled trials as the gold standard for causal evidence.
Longitudinal vs. Cross-Sectional Design
These are a temporal layer that overlaps with the four designs above. Cross-sectional studies collect data at one point in time; longitudinal studies track the same participants or cohort over time. Cross-sectional designs are faster and cheaper; longitudinal designs can detect change and, in some cases, establish temporal precedence, a prerequisite for causal claims in observational research.
Data Collection Methods and Measurement Scales
Core Collection Methods
Surveys and questionnaires are the most common quantitative method. Structured questions collect behaviors, attitudes, and knowledge using Likert scales, binary items, multiple-choice options, and semantic-differential scales. Pilot-test with a small group first to catch ambiguous items and timing problems.
Surveys can run online, on paper, by structured telephone interview, or in person.
Structured observation counts frequency of observable behaviors during defined time periods. Finalize coding rules before collection begins; verify inter-rater reliability (Cohen's kappa of 0.61 or more counts as substantial on the widely used Landis and Koch scale) before any data enters analysis.
Experiments manipulate conditions and observe outcomes. If random assignment is feasible, you can make causal claims. If not, you have a quasi-experiment.
Secondary data analysis uses existing datasets: school records, census data, clinical records, market databases. Researchers must understand original data production context before interpreting results; a billing database repurposed for research can introduce systematic biases the original design never anticipated.
Quantitative content analysis codes documents, articles, or media into defined categories, then counts and compares. The method requires standardized coding rules and inter-rater agreement checks across all coders.
Measurement Scale Rules
Match your statistical test to your measurement scale before anything else. Running a t-test on a single ordinal item (Likert 1–5) is a common shortcut that the conservative rule below forbids. The rule:
Scale
Examples
Permitted Statistics
Nominal
Gender, country, category
Mode, chi-square, frequencies
Ordinal
Likert 1–5, satisfaction rating
Median, IQR, Spearman ρ
Interval
Temperature (°C), IQ score
Mean, SD, Pearson r, t-test
Ratio
Height, weight, income, reaction time
All statistics
Statistical Analysis: Decision Framework and Benchmarks
The following table covers the tests most applied research scenarios need:
Nick Huntington-Klein (@nickchk) on regression worries that matter less than students think:
In regression, there are several things that students are eternally concerned about but are actually Just Fine:
1. Your coefficients don't need to be significant
2. Your R^2 doesn't need to be huge
3. Your predictors can be correlated
4. Your variables don't need to be normal
Reliability is not validity. A 2024 nursing research paper ranks designs by internal validity (is the causal inference warranted?) and flags threats to external validity (does it generalize?); construct validity asks whether your measurement actually reflects the concept. All three matter; a high Cronbach's α does not guarantee construct validity.
The p-Value Misconception
A p-value is the probability of observing a result at least as extreme as yours, assuming the null hypothesis is true. It is not the probability that your hypothesis is correct.
Pair every p-value with an effect size (Cohen's d, r, or η²) and a confidence interval. Large samples make trivial differences statistically significant.
Quantitative Research in UX and Product Design
Within the wider set of UX research methods, quantitative UX research covers:
Task completion rates: the percentage of participants who complete a defined task in a usability session. Binomial, so confidence intervals via the adjusted Wald method are more accurate than naive proportions for small samples.
System Usability Scale (SUS): a 10-item, 5-point Likert-format scale scored 0–100. The average across 500 studies is 68, and a score above 80.3 earns an A (the top 10% of scores) on MeasuringU's curved grading scale. Jeff Sauro and James Lewis's book Quantifying the User Experience is the standard practitioner reference.
A/B testing: an experimental design applied to product features. Requires a priori power analysis and full pre-specification of the primary metric before the test runs. Running an A/B test to "explore" and checking significance repeatedly as data accumulates is p-hacking.
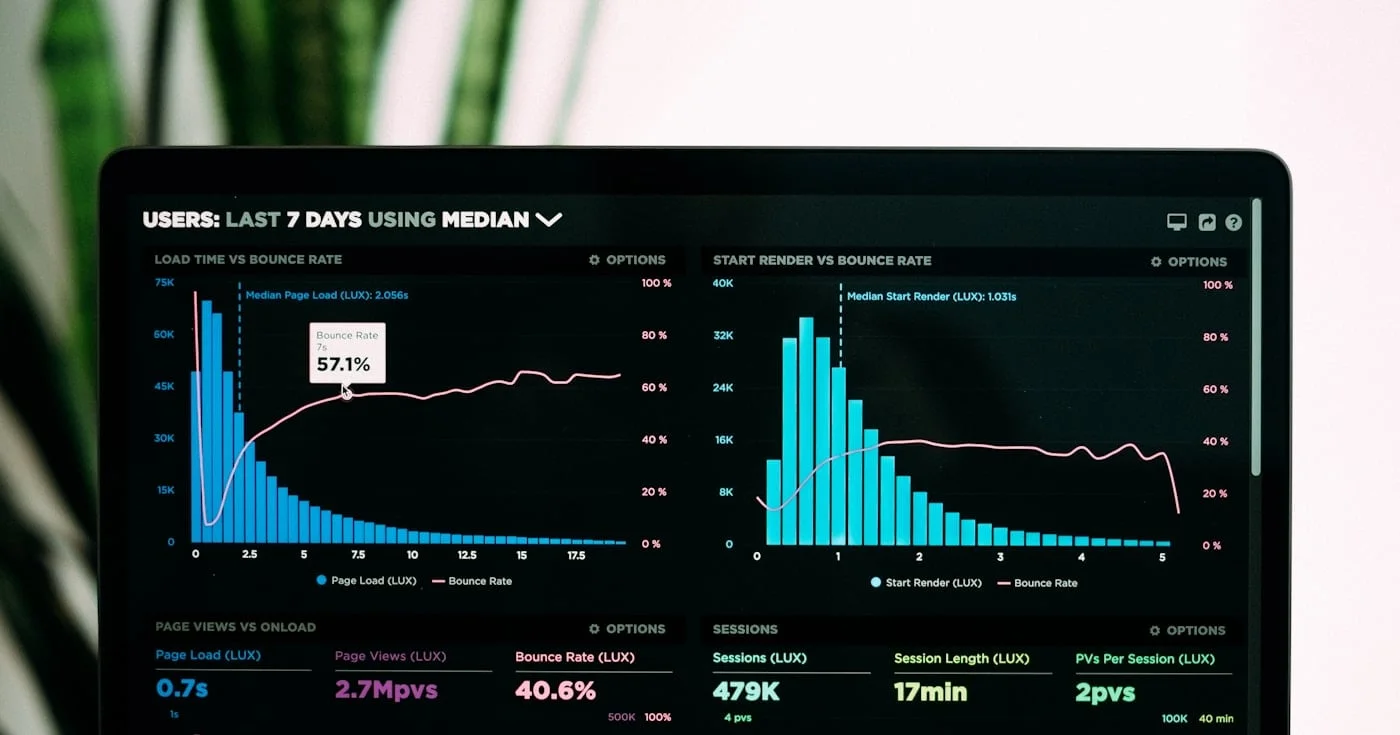
Log-data and clickstream analysis: behavioral data from production systems. Higher ecological validity than usability sessions; lower control. Funnel analysis, session recordings, and click heatmaps are all quantitative methods when analyzed with defined metrics and statistical thresholds.
SUPR-Q and other standardized scales: domain-specific instruments for website quality, perceived usability, and trust.
Nielsen Norman Group (@nngroup) on the gap between what users say and what they do:
Just asking users what they want isn’t enough.
What people say vs. what they do are different things. That’s why UX relies on:
✅ User interviews → Understand beliefs & goals
✅ Usability testing → Spot usability issues
Learn more: https://t.co/E3mpZ9Y5bg
#UserResearch https://t.co/C6k6ciPaSx
Surveys measure self-report; behavioral log data and task-based usability studies measure actual behavior. Quantitative UX methods that observe behavior carry more external validity than surveys for predicting how people actually use a product.
A practical skill-building path runs from surveys to usability metrics to log-data analysis to regression and statistical modeling, building toward what one commenter in the r/UXResearch thread above called a "heavy quant person."
Quantitative vs. Qualitative Research
Aspect
Quantitative
Qualitative
Main evidence
Numbers, scores, counts
Words, observations, meanings
Approach
Deductive (theory → test)
Inductive (data → theory)
Typical questions
How many? How much? How strong?
How? Why? What does it mean?
Sample size
Typically larger
Typically smaller
Data structure
Pre-defined, standardized
Emergent, flexible
Common analysis
Descriptive stats, tests, regression
Coding, themes, narrative
Generalizability
Higher (with probability sampling)
Lower (context-specific)
Strengths
Objective, replicable, scalable
Rich context, explores meaning
Limitations
May miss nuance; context-free
Subjective, not broadly generalizable
Mixed methods research combines both when the question needs both measurement and context. Three common designs: sequential explanatory (quant → qual, to explain the numbers), sequential exploratory (qual → quant, to develop an instrument), and concurrent triangulation (both simultaneously, comparing results).
Best Tools for Quantitative Research
A commenter in an r/sociology thread offered a useful heuristic for software selection: "If in academia for sociology, mostly Stata. If outside academia for social sciences, SPSS, then R. For 'data science' for profit, Python." (u/vnilaspce, October 2025 thread)
For UX teams specifically, Qualtrics and SurveyMonkey handle most survey infrastructure, while statistical analysis happens in R or Python depending on team background.
Common Quantitative Research Mistakes to Avoid
These eight mistakes are the ones practitioners flag most often.
Underpowered Studies: Collecting Data Before Powering the Study
Underpowered studies produce effect estimates that are too large (the "winner's curse") or miss real effects entirely. Run a priori power analysis before collection. Report achieved power alongside results.
Mismatching Statistical Test to Measurement Scale
Running a t-test on ordinal Likert data violates the test's assumptions. Always match test to scale using the decision table above. When normality or scale assumptions are violated, use the listed non-parametric alternatives.
P-Hacking and Selective Reporting
Testing multiple outcomes and reporting only the significant ones inflates Type I error. Pre-registration of hypotheses and analysis plans before data collection is the structural fix. Always report effect sizes and confidence intervals regardless of whether p < 0.05.
Ignoring Missing Data
Dropping incomplete cases (listwise deletion) biases results if the data are not missing completely at random. Diagnose the missingness mechanism (MCAR, MAR, or MNAR), then apply multiple imputation or maximum likelihood methods rather than deleting cases.
Overinterpreting Correlation as Causation
A correlational finding cannot establish which variable came first or whether a third variable caused both. State the design limitation explicitly in results. If causation is the actual question, you need either an experiment or a quasi-experimental design with appropriate controls (instrumental variables, propensity score matching).
Frank Harrell (@f2harrell), a Vanderbilt biostatistician, on how far bad practice reaches in observational research:
Statistical thought of the day: bad statistical practice is so pervasive in so much of observational research that correlation is not correlation.
When no real effects exist, running 20 tests at α = 0.05 produces one false positive on average. Apply Bonferroni correction (divide α by the number of tests) or Benjamini-Hochberg false discovery rate for large test families.
Starting With Data, Not a Research Question
Sean J. Taylor (@seanjtaylor) flagged this pattern directly:
When you start your research project with a data set rather than a research question. https://t.co/dr5Yal3dZ0
Post-hoc rationalization of hypotheses after seeing results ("HARKing," Hypothesizing After Results are Known) produces analysis that looks confirmatory but is exploratory.
Underpowered Interactions (Gelman's 16× Rule)
Andrew Gelman (@StatModeling), a Columbia statistician, on the sample cost of interactions:
You need 16 times the sample size to estimate an interaction than to estimate a main effect https://t.co/JzGyOIIDOY
His worked example assumes the interaction is half the size of the main effect: a study with 80% power for the main effect then has about 10% power for the interaction. Applied to a study sized at n = 64 per group for d = 0.5, matching that power for the interaction would take roughly 16 times as many participants (about 1,024 per group).
Statistical significance means a result would be rare if nothing changed. P-values, 0.05, practical vs statistical significance, and peeking's false positives.
The Kano model classifies how customers feel if a feature is present versus absent. Satisfaction does not rise in a straight line with more functionality.